Binary Search Tree in Java: Insert, Search, Delete and Traversal (with GTIN Example)
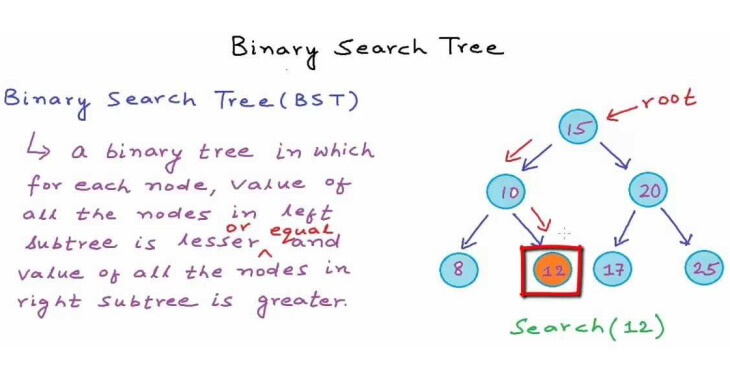
A binary search tree (BST) keeps its data sorted while still letting you insert and delete quickly. A sorted array finds an item fast with binary search, but inserting means shifting elements. A linked list inserts fast, but finding an item means walking the whole list. A balanced binary search tree does all three in O(log n) time.
This post builds a binary search tree in Java for a real task, a webshop that looks up products by their GTIN. You’ll learn:
- the tree terms you need, and the rule that makes a tree a search tree;
- insert, search and delete, with all three delete cases;
- in-order traversal, which returns the keys sorted;
- why an unbalanced tree is as slow as a list, measured with 1,000 keys;
- why in real code you should use Java’s
TreeMap.
All the code is Java, and every output in this post comes from running it on Java 25.
In this article 11 sections
Tree terminology
A tree is a data structure made of nodes connected by edges, where every node except the first has exactly one parent.
- The root is the top node, the only one without a parent.
- A node’s children are the nodes directly below it. A leaf is a node without children.
- A subtree is a node together with everything below it.
- The height of a tree is the number of nodes on the longest path from the root to a leaf.
In a binary tree, every node has at most two children, a left child and a right child.
A tree is also a special kind of graph: connected, with no cycles, so there’s exactly one path between any two nodes. For searching general graphs, see depth-first search in Java.
The binary search tree rule
A binary search tree is a binary tree where every node follows one rule:
- every key in its left subtree is smaller than its own key;
- every key in its right subtree is greater than its own key.
The rule applies to whole subtrees, not just to the direct children. It’s what makes searching fast: at every node, one comparison tells you which half of the remaining tree can contain the key, and you never look at the other half.
In this post every key is unique. Inserting a key that already exists replaces its value instead of adding a duplicate, which is also how Java’s TreeMap and HashMap behave.
The use case: looking up products by GTIN
The Global Trade Item Number (GTIN) is the number behind a product’s barcode. A webshop wants to find a product by its GTIN quickly.
The GTINs in this post are 14-digit strings, so comparing them as strings with compareTo gives the same order as comparing them as numbers. That only works because they all have the same length; with different lengths, "9" would sort after "10".
The product is a record, and each tree node holds one product plus links to its two children:
1
public record Product(String gtin, String name) {}
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
public class ProductTree {

  private static class Node {
    final String gtin;
    Product product;
    Node left;
    Node right;

    Node(Product product) {
      this.gtin = product.gtin();
      this.product = product;
    }
  }

  private Node root;
}
Insert
To insert, start at the root and go left or right at each node until you find an empty spot:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
public void insert(Product product) {
  Node newNode = new Node(product);
  if (root == null) {
    root = newNode;
    return;
  }
  Node current = root;
  while (true) {
    int cmp = product.gtin().compareTo(current.gtin);
    if (cmp == 0) {               // GTIN already in the tree: replace the product
      current.product = product;
      return;
    }
    if (cmp < 0) {
      if (current.left == null) {
        current.left = newNode;
        return;
      }
      current = current.left;
    } else {
      if (current.right == null) {
        current.right = newNode;
        return;
      }
      current = current.right;
    }
  }
}
The earlier version of this post had a bug here. Its “already exists” branch was an else without braces, so the return after it ran on every step down the tree, and every node deeper than the root’s children was silently dropped. I ran it: of the 6 GTINs in the test below, only the first 2 were stored. Always use braces, and always test a tree with more than two levels.
Search
Search follows the same path as insert, and stops when it finds the key or falls off the tree:
1
2
3
4
5
6
7
8
9
public Product find(String gtin) {
  Node current = root;
  while (current != null) {
    int cmp = gtin.compareTo(current.gtin);
    if (cmp == 0) return current.product;
    current = cmp < 0 ? current.left : current.right;
  }
  return null; // not in the tree
}
This test inserts five products, checks that a sixth GTIN isn’t there yet, inserts it, and finds it:
1
2
3
4
5
6
7
8
9
10
11
12
@Test
void findsProductByGtin() {
  tree.insert(new Product("04000345706564", "Product A"));
  tree.insert(new Product("07611400983416", "Product B"));
  tree.insert(new Product("07611400989104", "Product C"));
  tree.insert(new Product("07611400989111", "Product D"));
  tree.insert(new Product("07611400990292", "Product E"));
  assertNull(tree.find("07611400983324"));

  tree.insert(new Product("07611400983324", "Product F"));
  assertEquals("Product F", tree.find("07611400983324").name());
}
All six GTINs are found. The number of comparisons is the depth of each node: 1 for the root 04000345706564, and 5 for 07611400990292, the deepest.
Balanced and unbalanced trees
The shape of a binary search tree depends on the order in which you insert the keys. The test inserts the GTINs almost in sorted order, so each new key goes to the right of the previous one, and the tree leans right with a height of 5. The same 6 GTINs inserted median first build a tree of height 3:
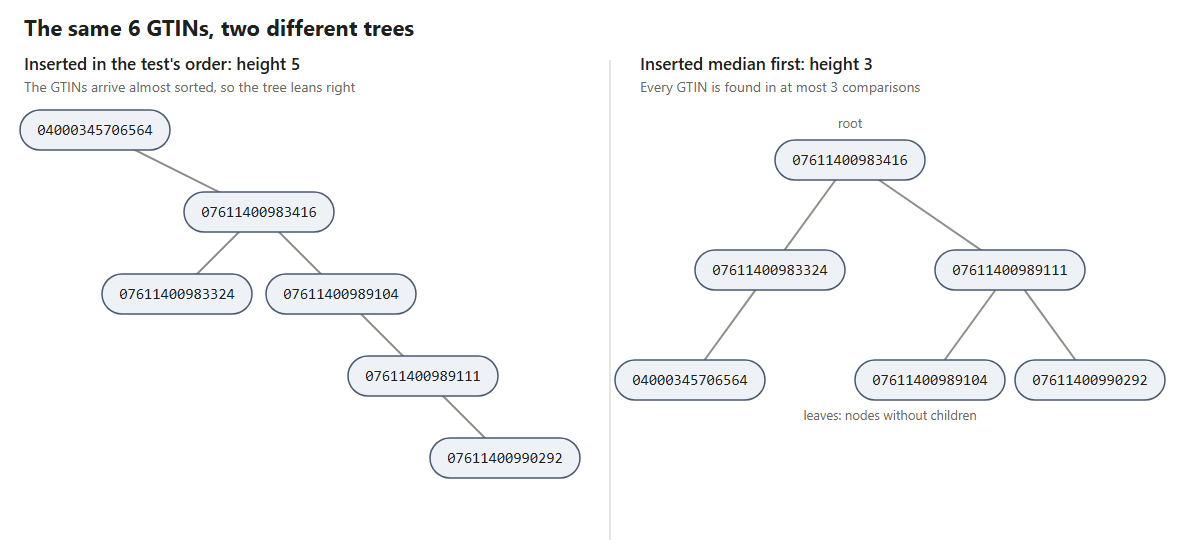
With 6 keys the difference is small. With more keys it becomes dramatic. I inserted 1,000 random 14-digit GTINs into two trees, the first in random order and the second already sorted, and searched for every key:
| Insertion order | Tree height | Worst search | Average search |
|---|---|---|---|
| Random | 25 | 25 comparisons | 12.5 comparisons |
| Sorted | 1,000 | 1,000 comparisons | 500.5 comparisons |
With sorted input, every node has only a right child, so the tree is a linked list and every search is a linear scan. Random order gave heights between 20 and 25 in my runs; a perfectly balanced tree of 1,000 keys has height 10, because ⌊log₂ 1,000⌋ + 1 = 10.
That’s why the speed of a plain binary search tree is O(log n) only on average. In the worst case, which happens with sorted or nearly sorted input, a common situation for IDs, dates and GTINs, it’s O(n). For a billion products, that’s the difference between 30 comparisons and a billion.
Self-balancing trees fix this. After each insert or delete, they rotate nodes to keep the height close to log₂ n. The two classic ones are the AVL tree and the red-black tree. You rarely need to write one: Java already has one.
Binary search trees, red-black trees and the analysis behind them are covered in depth in Algorithms by Robert Sedgewick and Kevin Wayne. Its searching chapter builds a BST and then a red-black tree in Java, step by step, and it’s one of the clearest explanations of balancing you’ll find.
Delete
Deleting is the hardest operation, because the tree must keep the binary search tree rule. There are three cases:
- The node has no children: remove it.
- The node has one child: replace the node with its child.
- The node has two children: replace it with its successor, the smallest key in its right subtree. The successor is bigger than everything on the left and smaller than everything else on the right, so the rule still holds.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
public void delete(String gtin) {
  root = delete(root, gtin);
}

private Node delete(Node node, String gtin) {
  if (node == null) return null;             // not found
  int cmp = gtin.compareTo(node.gtin);
  if (cmp < 0) {
    node.left = delete(node.left, gtin);
    return node;
  }
  if (cmp > 0) {
    node.right = delete(node.right, gtin);
    return node;
  }
  if (node.left == null) return node.right;  // cases 1 and 2
  if (node.right == null) return node.left;  // case 2
  Node successor = node.right;               // case 3
  while (successor.left != null) {
    successor = successor.left;
  }
  successor.right = deleteMin(node.right);
  successor.left = node.left;
  return successor;
}

private Node deleteMin(Node node) {
  if (node.left == null) return node.right;
  node.left = deleteMin(node.left);
  return node;
}
With short numeric keys it’s easier to follow. Starting from a tree with the keys 50, 30, 70, 20, 40, 60, 80 and 65, deleting 20 (no children), then 60 (one child), then the root 50 (two children):
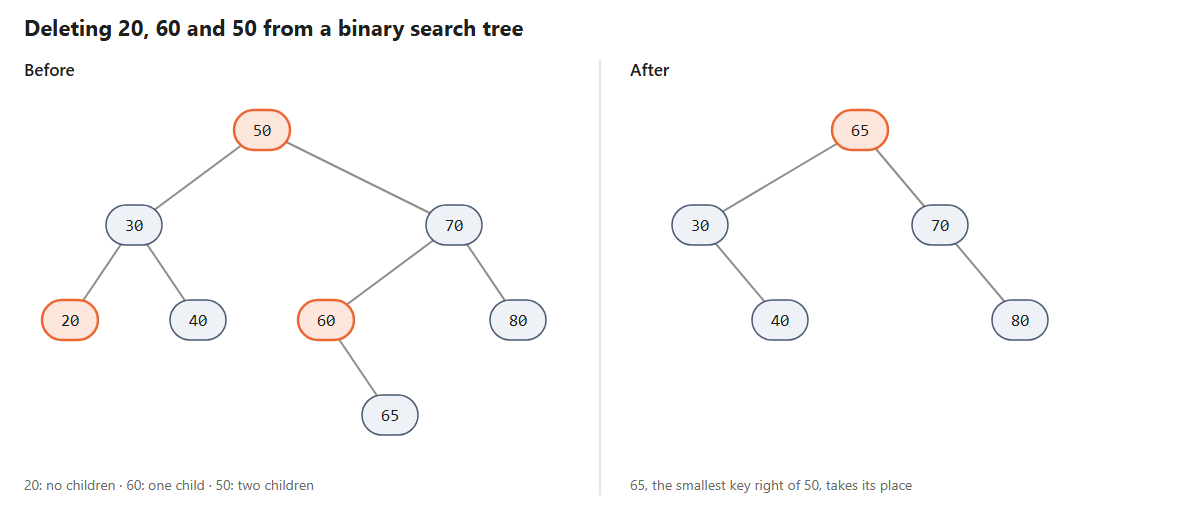
After the three deletions, the tree contains 30, 40, 65, 70 and 80, still in binary search tree order, with 65 as the new root. Deleting a key that isn’t in the tree changes nothing.
In-order traversal: the keys in sorted order
An in-order traversal visits the left subtree, then the node, then the right subtree. In a binary search tree, that visits the keys in sorted order:
1
2
3
4
5
6
7
8
9
10
11
12
public List<String> inOrder() {
  List<String> gtins = new ArrayList<>();
  inOrder(root, gtins);
  return gtins;
}

private void inOrder(Node node, List<String> gtins) {
  if (node == null) return;
  inOrder(node.left, gtins);
  gtins.add(node.gtin);
  inOrder(node.right, gtins);
}
For the GTIN tree it returns:
1
[04000345706564, 07611400983324, 07611400983416, 07611400989104, 07611400989111, 07611400990292]
The other two depth-first orders are pre-order (node, left, right), which is useful to copy or serialize a tree, and post-order (left, right, node), which is useful to delete one, because children are handled before their parent.
In real code, use TreeMap
Java’s TreeMap is a red-black tree, so it stays balanced whatever the insertion order. It does everything above in guaranteed O(log n) time, plus range queries that a HashMap can’t do:
1
2
3
4
5
6
7
8
TreeMap<String, Product> catalog = new TreeMap<>();
catalog.put("04000345706564", new Product("04000345706564", "Product A"));
// ... the other five products

catalog.get("07611400989111");                     // Product D
catalog.subMap("07611400", "07611401").keySet();   // every GTIN that starts with 07611400
catalog.ceilingKey("07611400985000");              // 07611400989104, the next GTIN
catalog.floorKey("07611400985000");                // 07611400983416, the previous GTIN
subMap("07611400", "07611401") returns the 5 GTINs that start with 07611400, because in a sorted map they’re all next to each other. After its first digit, a 14-digit GTIN contains the GS1 company prefix of the brand owner, so a range query like this can find all the products of one company, as long as you know its prefix.
Use a HashMap when you only need lookups by exact key: it’s O(1) on average. Use a TreeMap when you also need the keys in order, the smallest or largest key, or a range. To see how these choices affect speed, see Big O notation in Java.
Complexity
| Operation | Balanced BST, TreeMap |
Unbalanced BST (worst case) |
|---|---|---|
| Search | O(log n) | O(n) |
| Insert | O(log n) | O(n) |
| Delete | O(log n) | O(n) |
| In-order traversal | O(n) | O(n) |
| Minimum, maximum, next key | O(log n) | O(n) |
The tree uses O(n) memory for its nodes. The recursive methods also use stack space proportional to the height: O(log n) in a balanced tree, but O(n) in a degenerate one, where a deep enough tree can throw a StackOverflowError.
FAQ
What is the difference between a binary tree and a binary search tree?
A binary tree only limits each node to two children. A binary search tree adds the ordering rule: smaller keys on the left, greater keys on the right. Only the binary search tree lets you search by discarding half of the tree at every step.
Is a binary search tree always O(log n)?
No. It’s O(log n) when the tree is balanced, which is likely with random insertion order. With sorted or nearly sorted input it becomes a linked list, and operations are O(n). Self-balancing trees, such as Java’s TreeMap, guarantee O(log n).
How do you handle duplicate keys?
Either replace the value, as TreeMap does and as this post does, or store a list of values in each node, or decide that equal keys always go to one side, for example the right. Choose one rule and use it in insert, search and delete.
How do you check whether a binary tree is a valid BST?
Pass an allowed range down the tree: the root can be anything, its left child must be smaller than the root, its right child greater, and so on. Checking only that each child is on the right side of its parent isn’t enough, because the rule applies to whole subtrees. This is a classic interview question.
When should I use a TreeMap instead of a HashMap?
When you need the keys sorted, or queries like first, last, next greater than, or all keys between A and B. For lookups by exact key only, a HashMap is faster.
Trees show up in coding interviews all the time, often in questions about traversal, validation and balance. To practice the whole interview, from the first idea to working Java code, see my book THE CODE INTERVIEW: Real Java Coding Interview Questions, Solved Step by Step.
“If this article helped you, help me create the next one.”
☕ Buy me a coffee