Big O Notation in Java: Time and Space Complexity for Coding Interviews
Big O notation describes how the running time or the memory of an algorithm grows when its input grows. An algorithm that is fast for 100 users can be unusable for 10 million, and Big O is how you see that before it happens.
It’s also one of the most common topics in coding interviews: after almost every solution, the interviewer asks “What’s the time and space complexity?” This post gives you the answer for the patterns you’ll meet, with Java examples that I compiled and ran on Java 25. You’ll learn:
- what Big O, Big Omega and Big Theta mean, and how they differ from best and worst cases;
- the common complexity classes, from O(1) to O(n!), each with a Java example;
- how to count the steps of an algorithm, and why Big O drops constants;
- space complexity, and the Big O of the Java collections you use every day;
- how to check a complexity with a stopwatch, using a doubling test.
The analysis of algorithms as a field goes back to Donald Knuth’s The Art of Computer Programming, whose first volume appeared in 1968.
In this article 9 sections
Big O, Big Omega and Big Theta
Time complexity measures how many steps an algorithm takes. Space complexity measures how much extra memory it needs. Both are expressed as a function of the input size n, such as the number of items in an array.
There are three notations:
- Big O, O(f(n)): an upper bound. The algorithm grows no faster than f(n). In interviews, “the complexity” almost always means the Big O of the worst case.
- Big Omega, Ω(f(n)): a lower bound. The algorithm needs at least f(n) steps.
- Big Theta, Θ(f(n)): a tight bound. The algorithm grows exactly like f(n), because f(n) is both an upper and a lower bound.
Don’t confuse these notations with the best, average and worst cases. The cases describe which input you analyze; the notations describe how you bound its running time. A linear search takes O(1) time in the best case, when the item is the first one, and O(n) time in the worst case, when the item is the last one or missing.
Big O questions rarely come alone in an interview: you write a solution, then explain its complexity, then improve it. My book The Code Interview collects real Java coding interview questions and solves them step by step, so you can practice that whole conversation, not just the final code.
The common complexity classes
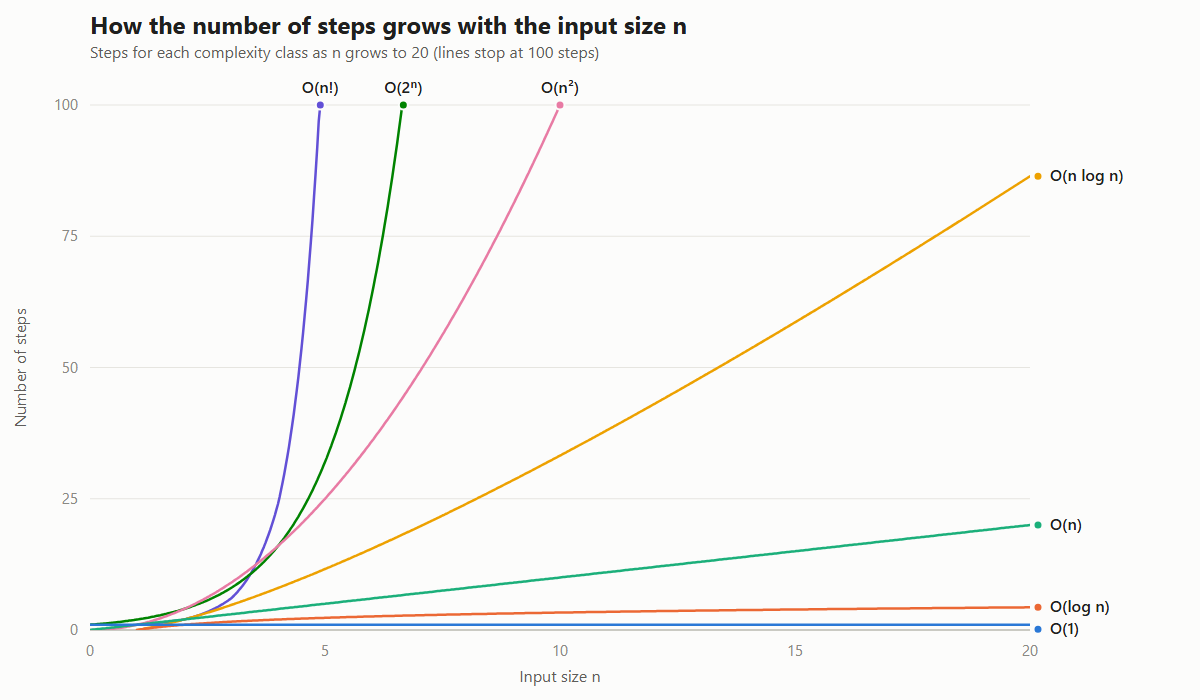
The chart shows how the number of steps grows for each class as n goes from 0 to 20. The differences are already huge at this tiny size: O(n!) passes 100 steps before n = 5, while O(log n) needs fewer than 5 steps at n = 20.
| Big O | Name | Java example | n = 1,000 means about |
|---|---|---|---|
| O(1) | Constant | array[i], ArrayList.get(i) |
1 step |
| O(log n) | Logarithmic | Binary search | 10 steps |
| O(n) | Linear | One loop over the input | 1,000 steps |
| O(n log n) | Linearithmic | Merge sort, List.sort |
10,000 steps |
| O(n²) | Quadratic | Two nested loops | 1,000,000 steps |
| O(n³) | Cubic | Three nested loops | 1,000,000,000 steps |
| O(2ⁿ) | Exponential | Naive recursive Fibonacci | more than the atoms in the universe |
| O(n!) | Factorial | All permutations | even more |
O(1): constant time
The running time doesn’t depend on the input size. Reading an array element or adding to the end of an ArrayList takes the same time whether the list has 10 or 10 million items.
1
2
3
public void addItem(List<String> list, String item) {
  list.add(item);
}
Strictly, ArrayList.add is O(1) amortized. When the internal array is full, Java copies all items into a larger array, which costs O(n). Because the array grows by half its size each time, this happens rarely enough that the average cost per add stays constant.
O(n): linear time
The number of steps grows in proportion to the input. Looping over an array once is the typical example:
1
2
3
4
5
6
7
public int sum(int[] numbers) {
  int sum = 0;
  for (int number : numbers) {
    sum += number;
  }
  return sum;
}
If numbers has n elements, the loop body runs n times, so the method is O(n).
Improving an algorithm usually means removing steps. For an example, see find the smallest number with the same number of digits, where counting down one number at a time is replaced by a direct calculation from the number of digits.
O(n²): quadratic time
Two nested loops over the same input give n × n steps. Initializing an n × n tic-tac-toe board is quadratic:
1
2
3
4
5
6
7
8
9
10
private String[][] board;

public void initializeBoard(int size) {
  board = new String[size][size];
  for (int x = 0; x < size; x++) {
    for (int y = 0; y < size; y++) {
      board[x][y] = " ";
    }
  }
}
So is printing every pair of elements of an array:
1
2
3
4
5
6
int[] numbers = {1, 2, 3, 4, 5};
for (int i = 0; i < numbers.length; i++) {
  for (int j = 0; j < numbers.length; j++) {
    System.out.println(numbers[i] + " " + numbers[j]);
  }
}
Both loops run n times, so the body runs n × n = n² times.
O(n³): cubic time
Three nested loops give n × n × n steps. A classic example is three-sum: given n integers, count the triples that add up to exactly zero. The brute-force solution checks every triple:
1
2
3
4
5
6
7
8
9
10
public int countThreeSum(int[] numbers) {
  int n = numbers.length;
  int count = 0;
  for (int i = 0; i < n; i++)
    for (int j = i + 1; j < n; j++)
      for (int k = j + 1; k < n; k++)
        if (numbers[i] + numbers[j] + numbers[k] == 0)
          count++;
  return count;
}
The inner if runs once for every triple, n(n − 1)(n − 2) / 6 times, which is O(n³). For {30, -40, -20, -10, 40, 0, 10, 5} it returns 4. Later in this post you’ll time this method and watch the cubic growth happen.
O(log n): logarithmic time
A logarithmic algorithm halves the problem at every step. Its curve rises quickly for small inputs and then flattens: doubling the input adds only one more step. Binary search on a sorted array is the standard example:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
public int binarySearch(int[] sorted, int target) {
  int left = 0;
  int right = sorted.length - 1;
  while (left <= right) {
    int mid = left + (right - left) / 2;
    if (sorted[mid] == target) {
      return mid;
    } else if (sorted[mid] < target) {
      left = mid + 1;
    } else {
      right = mid - 1;
    }
  }
  return -1; // not found
}
In the worst case, binary search looks at ⌊log₂ n⌋ + 1 elements. I checked every possible target:
| Array size n | log₂ n | Worst-case comparisons |
|---|---|---|
| 8 | 3 | 4 |
| 16 | 4 | 5 |
| 1,000 | 9.97 | 10 |
| 1,000,000 | 19.93 | 20 |
A million sorted elements need at most 20 comparisons, while a linear search may need a million. mid = left + (right - left) / 2 avoids the integer overflow that (left + right) / 2 causes on very large arrays. The same halving idea is behind the binary search tree.
O(n log n): linearithmic time
Merge sort splits the array in half until each part has one element, then merges the sorted halves. There are log₂ n levels of splitting, and each level merges all n elements, so it takes O(n log n) time:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
public void mergeSort(int[] a) {
  if (a.length < 2) return;
  int mid = a.length / 2;
  int[] left = Arrays.copyOfRange(a, 0, mid);
  int[] right = Arrays.copyOfRange(a, mid, a.length);
  mergeSort(left);
  mergeSort(right);

  int i = 0, j = 0, k = 0;
  while (i < left.length && j < right.length) {
    a[k++] = left[i] <= right[j] ? left[i++] : right[j++];
  }
  while (i < left.length) a[k++] = left[i++];
  while (j < right.length) a[k++] = right[j++];
}
O(n log n) is the best possible for sorting by comparing elements, and it’s what Java’s List.sort and Arrays.sort guarantee. The merge step on its own is linear; see merge two sorted lists.
O(2ⁿ): exponential time
The naive recursive Fibonacci calls itself twice for each number:
1
2
3
public long fib(int n) {
  return n < 2 ? n : fib(n - 1) + fib(n - 2);
}
Each call starts two more, so the number of calls roughly doubles with each step of n. I counted them: fib(10) makes 177 calls, fib(20) makes 21,891, and fib(30) makes 2,692,537. Adding memoization, which stores each result the first time it’s computed, makes it O(n):
1
2
3
4
5
public long fib(int n, long[] memo) {
  if (n < 2) return n;
  if (memo[n] != 0) return memo[n];
  return memo[n] = fib(n - 1, memo) + fib(n - 2, memo);
}
With new long[51], fib(50, memo) returns 12,586,269,025 instantly. The naive version would need about 40 billion calls.
O(n!): factorial time
Generating every ordering of n items produces n! results, so it can’t be faster than O(n!):
1
2
3
4
5
6
7
8
9
public void permutations(String prefix, String rest, List<String> out) {
  if (rest.isEmpty()) {
    out.add(prefix);
    return;
  }
  for (int i = 0; i < rest.length(); i++) {
    permutations(prefix + rest.charAt(i), rest.substring(0, i) + rest.substring(i + 1), out);
  }
}
"abcd" has 4! = 24 permutations. Ten letters have 3,628,800, and twenty have more than 2 × 10¹⁸. Brute-force solutions to problems like the traveling salesman are factorial, which is why they only work for tiny inputs.
How to find the complexity of an algorithm
You find the Big O in two steps: count how many times each operation runs, then keep only the term that grows fastest.
Take this method, which adds the even numbers from 1 to N:
1
2
3
4
5
6
7
public int sumEvenNumbers(int N) {
  int sum = 0;
  for (int number = 1; number <= N; number++)
    if (number % 2 == 0)
      sum = sum + number;
  return sum;
}
Count each operation:
| Operation | Runs |
|---|---|
int sum = 0 |
1 |
int number = 1 |
1 |
number <= N |
N + 1 (the last check ends the loop) |
number++ |
N |
number % 2 == 0 |
N |
sum = sum + number |
N / 2 (only for even numbers) |
return sum |
1 |
The total for an even N is 1 + 1 + (N + 1) + N + N + N/2 + 1 = 3.5N + 4. I added counters to the method to check it: for N = 1,000 it runs exactly 3,504 operations.
To turn 3.5N + 4 into Big O, apply two rules:
- Drop the lower-order terms: 3.5N + 4 becomes 3.5N.
- Drop the constant factors: 3.5N becomes N.
So sumEvenNumbers is O(n). The same rules turn 2n³ + 4n + 3 into O(n³).
In an interview you don’t need the exact count; you need the structure. One loop over the input is O(n), a loop inside a loop is O(n²), and halving the input in each step gives O(log n). Counting precisely is how you check that your shortcut is right.
Why Big O ignores constants
Constants do matter for small inputs. Compare an algorithm that takes 100n steps with one that takes n² steps:
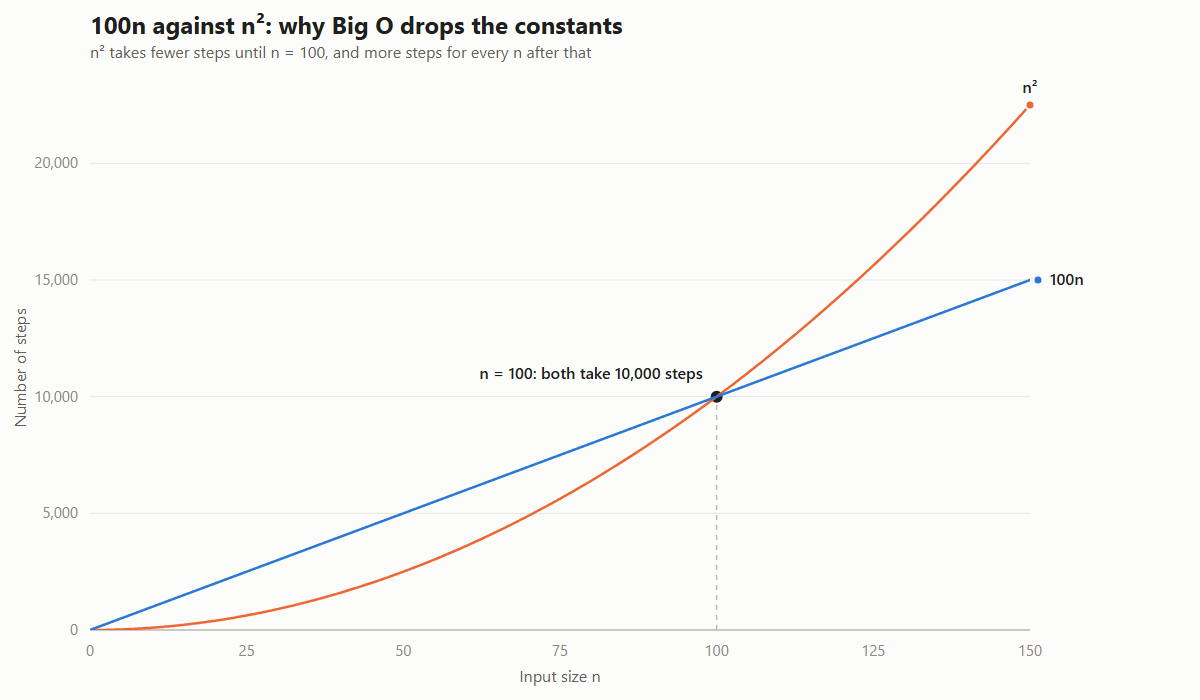
For n below 100, the n² algorithm takes fewer steps. At n = 100, both take 10,000 steps. After that, n² is slower for every larger input, and the gap keeps widening: at n = 10,000, 100n takes 1 million steps and n² takes 100 million.
Big O describes this long-term behavior. Whatever the constant, a linear algorithm eventually beats a quadratic one, so 100n is written as O(n). When your inputs are guaranteed to be small, the constants can matter more than the Big O, which is why Java’s sorting switches to insertion sort, an O(n²) algorithm, for very short arrays.
Space complexity
Space complexity counts the extra memory an algorithm needs, not including the input. It follows the same rules as time complexity.
| Example | Extra space | Why |
|---|---|---|
sum(int[] numbers) |
O(1) | One int, whatever the input size |
Iterative binarySearch |
O(1) | Three int variables |
mergeSort |
O(n) | The left and right copies |
Memoized fib(n, memo) |
O(n) | The memo array and n stack frames |
Naive recursive fib(n) |
O(n) | Up to n calls on the stack at once |
Recursion uses stack memory even when you don’t create any objects: each call that hasn’t returned yet holds a stack frame. That’s why deep recursion can throw a StackOverflowError, and why the naive fib uses O(n) space even though it creates nothing.
Interviewers often ask you to trade one for the other. Memoized Fibonacci spends O(n) memory to go from O(2ⁿ) to O(n) time.
Big O of Java collections
Most complexity questions in Java interviews come down to choosing the right collection. These are the costs of the common operations:
| Collection | Access / search | Add | Remove | Notes |
|---|---|---|---|---|
ArrayList |
get(i) O(1), contains O(n) |
At the end O(1) amortized, at index i O(n) | At index i O(n) | Elements after i are shifted |
LinkedList |
get(i) O(n), contains O(n) |
At either end O(1) | At either end O(1) | Slow random access |
ArrayDeque |
peekFirst/peekLast O(1) |
At either end O(1) amortized | At either end O(1) | The best stack and queue |
HashMap / HashSet |
get, containsKey O(1) on average |
put O(1) on average |
O(1) on average | Slower when many keys collide |
TreeMap / TreeSet |
get, containsKey O(log n) |
O(log n) | O(log n) | Keys kept sorted |
PriorityQueue |
peek O(1), contains O(n) |
offer O(log n) |
poll O(log n) |
A binary heap |
List.sort, Arrays.sort |
O(n log n) |
The most common mistake is calling list.contains(x) inside a loop. That makes the loop O(n²). Putting the items in a HashSet first makes each lookup O(1) and the whole loop O(n). For a worked example, see transform a list into a HashMap, and for how these structures work inside, see data structures: the foundation of efficient programming.
Measure it yourself: the doubling test
You can check a complexity with a stopwatch. Run the algorithm, double the input size, and run it again. The ratio between the two times tells you the growth rate:
- O(n): the time doubles (ratio 2);
- O(n²): the time grows four times (ratio 4);
- O(n³): the time grows eight times (ratio 8).
I timed countThreeSum and sum on random input with Java 25. Your times will differ on another machine, but the ratios won’t:
countThreeSum, n |
Time | Ratio |
|---|---|---|
| 500 | 13.2 ms | |
| 1,000 | 106.4 ms | 8.0 |
| 2,000 | 852.6 ms | 8.0 |
| 4,000 | 6,735.1 ms | 7.9 |
sum, n |
Time | Ratio |
|---|---|---|
| 25,000,000 | 5.6 ms | |
| 50,000,000 | 10.9 ms | 2.0 |
| 100,000,000 | 24.5 ms | 2.2 |
| 200,000,000 | 46.7 ms | 1.9 |
The three-sum time is multiplied by 8 at every doubling, exactly what O(n³) predicts. At this rate, n = 8,000 would take almost a minute, and n = 1,000,000 would take years. The sum time doubles, as O(n) predicts.
The doubling test is how Robert Sedgewick and Kevin Wayne teach algorithm analysis in Algorithms. Their book starts from experiments like this one, builds mathematical models from them, and then covers sorting, searching, graphs and strings in Java. It’s the best next step if you want to go deeper than this post.
How to answer complexity questions in an interview
- State both time and space, for example “O(n) time and O(1) extra space”.
- Name what n is. For two inputs, use two variables: merging two lists is O(n + m), not O(n).
- Explain where the number comes from: “one pass over the array, and each HashSet lookup is O(1) on average.”
- Mention the worst case when it differs from the average, as with
HashMapor quicksort. - Offer the trade-off: a faster solution that uses more memory, or the reverse.
- Say when constants matter: for small, bounded inputs, a simple O(n²) solution can be the right choice.
FAQ
What is Big O notation in simple terms?
Big O tells you how the work an algorithm does grows when its input grows. O(n) means that doubling the input roughly doubles the work, and O(n²) means that doubling the input roughly quadruples it.
Is O(log n) faster than O(1)?
No. O(1) takes the same time for any input size, while O(log n) grows slowly as the input grows. In practice O(log n) is very fast: about 30 steps for a billion elements.
What is the difference between Big O and Big Theta?
Big O is an upper bound, and Big Theta is a tight bound. Linear search is O(n) and also O(n²), because both are upper bounds, but it’s Θ(n) in the worst case. In interviews, people say Big O and usually mean the tight worst-case bound.
Is HashMap.get always O(1)?
It’s O(1) on average. If many keys land in the same bucket, lookups get slower. Since Java 8, a bucket with many entries is turned into a balanced tree, which keeps the worst case at O(log n) when the keys are Comparable.
Do I count the input in space complexity?
Usually not. Space complexity in interviews means extra space. Say it explicitly: “O(1) extra space, not counting the input array.”
Big O becomes natural with practice. Write a solution, state its complexity, then try to beat it. For real Java coding interview questions to practice on, each solved step by step, see my book The Code Interview.
“If this article helped you, help me create the next one.”
☕ Buy me a coffee