Depth-First Search (DFS) in Java: Graph Traversal Explained, with BFS
Depth-first search (DFS) is an algorithm for visiting every node of a graph. It starts at one node and follows one path as deep as it can before it backs up and tries the next path. It answers questions like “which cities can I reach from Berlin?”, “is there a route from Berlin to München?” and “does this network contain a cycle?”
This post explains graphs and DFS with one example, a Hyperloop network between 12 German cities. You’ll learn:
- the graph terms you need, such as adjacency, paths, cycles and connected graphs;
- how to store a graph in Java, as an adjacency list or an adjacency matrix;
- DFS in Java, both iterative and recursive, and its complexity;
- how to find a path with DFS, and why breadth-first search (BFS) finds the shortest one;
- what DFS is used for: connected components, cycle detection and ordering tasks.
All the code is Java, and every output in this post comes from running it on Java 25.
In this article 9 sections
What is a graph?
A graph is a set of vertices (also called nodes) connected by edges. Unlike a list or a tree, a graph has no fixed shape: it takes the shape of the problem. If the vertices are cities, the edges can be routes between them. If the vertices are the tasks of a project, the edges can say which task must be done before another.
Graph theory started in 1736, when Leonhard Euler proved that nobody could walk through the city of Königsberg crossing each of its seven bridges exactly once.
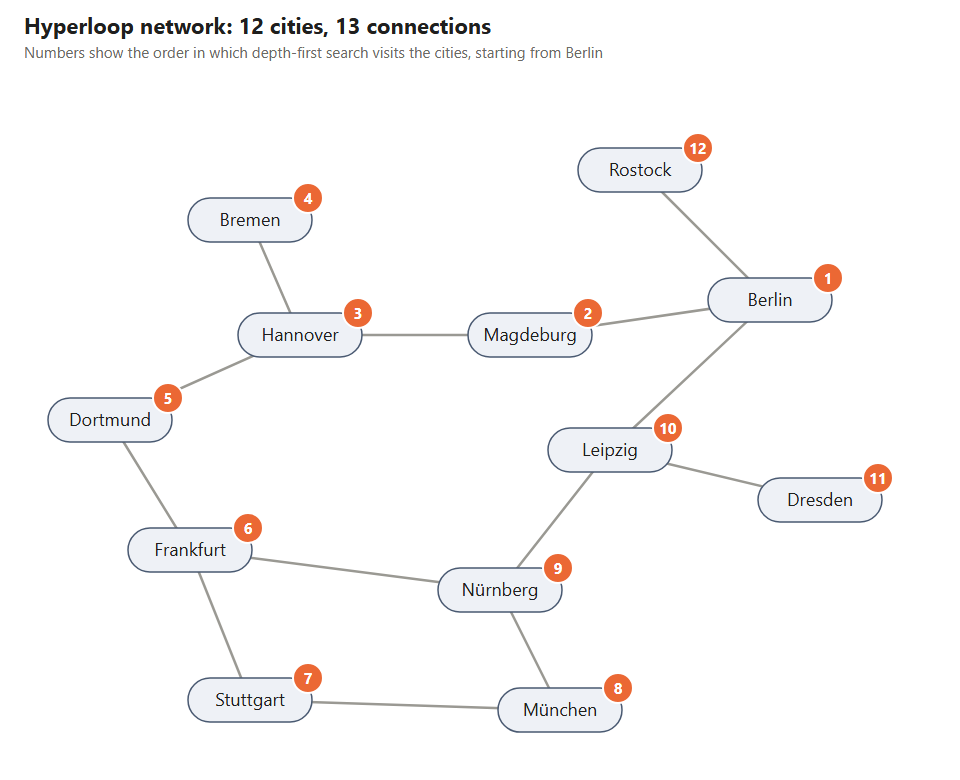
This is the Hyperloop network we’ll use. Each city is a vertex and each connection is an edge. The numbers show the order in which DFS visits the cities, which you’ll see in a moment.
Graph terminology
Adjacent vertices. Two vertices connected by one edge are adjacent, or neighbors. Berlin and Leipzig are adjacent; Berlin and Dresden are not.
Path. A path is a sequence of vertices where each one is adjacent to the next. Berlin, Leipzig, Nürnberg, München is a path from Berlin to München.
Connected graph. A graph is connected if there is a path between every pair of vertices. Our network is connected: you can reach every city from every other city.
Directed and undirected graphs. In a directed graph, each edge has a direction, like a one-way street. Our network is undirected: a Hyperloop that goes from Berlin to Leipzig also goes from Leipzig to Berlin.
Weighted graphs. In a weighted graph, each edge has a value, such as a distance, a travel time or a price. Our network is unweighted: we only care whether two cities are connected.
Cycles. A cycle is a path that starts and ends at the same vertex without reusing an edge. Frankfurt, Nürnberg, München, Stuttgart and back to Frankfurt is a cycle. A graph without cycles is acyclic. A connected, undirected, acyclic graph is a tree: every pair of vertices is joined by exactly one path.
The cycles are why DFS must remember which cities it has already visited. Without that, it would go round the Frankfurt–Nürnberg–München–Stuttgart loop forever.
Storing a graph in Java
There are two common ways to store which vertices are connected.
Adjacency matrix. For n vertices, an n × n table of booleans or 0s and 1s: matrix[i][j] is 1 when vertex i is connected to vertex j. Checking whether two cities are connected is O(1), but the table always uses n² cells, even when most cities have only two or three connections. Finding a city’s neighbors means scanning its whole row.
Adjacency list. For each vertex, a list of its neighbors. It uses memory in proportion to the number of vertices plus the number of edges, and listing a city’s neighbors costs only as many steps as it has neighbors.
| Adjacency matrix | Adjacency list | |
|---|---|---|
| Memory | O(V²) | O(V + E) |
| Are two vertices connected? | O(1) | O(degree) |
| List the neighbors of a vertex | O(V) | O(degree) |
| Best for | Dense graphs, small fixed size | Sparse graphs, like most real networks |
V is the number of vertices, E the number of edges, and the degree of a vertex is its number of neighbors. Road, rail and social networks are sparse, so the adjacency list is the usual choice. With Java’s collections, it’s a map from each city to the list of its neighbors:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
public class Graph {

  private final Map<String, List<String>> adjacency = new LinkedHashMap<>();

  public void addCity(String city) {
    adjacency.putIfAbsent(city, new ArrayList<>());
  }

  public void addConnection(String city1, String city2) {
    addCity(city1);
    addCity(city2);
    adjacency.get(city1).add(city2); // undirected: add the edge in both directions
    adjacency.get(city2).add(city1);
  }
}
A LinkedHashMap keeps the cities in the order you added them, so the traversal order in the examples below is predictable. The network is built from 13 connections:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
Graph graph = new Graph();
graph.addConnection("Berlin", "Magdeburg");
graph.addConnection("Berlin", "Leipzig");
graph.addConnection("Berlin", "Rostock");
graph.addConnection("Leipzig", "Dresden");
graph.addConnection("Leipzig", "Nürnberg");
graph.addConnection("Nürnberg", "München");
graph.addConnection("Magdeburg", "Hannover");
graph.addConnection("Hannover", "Bremen");
graph.addConnection("Hannover", "Dortmund");
graph.addConnection("Dortmund", "Frankfurt");
graph.addConnection("Frankfurt", "Stuttgart");
graph.addConnection("Frankfurt", "Nürnberg");
graph.addConnection("Stuttgart", "München");
Berlin’s neighbors are now [Magdeburg, Leipzig, Rostock], in that order. For more on choosing between these structures, see data structures: the foundation of efficient programming.
Depth-first search in Java
DFS uses a stack, a last-in, first-out structure: the city added last is the first one taken out. That’s what makes it go deep. It always continues from the city it reached most recently.
- Push the start city onto the stack.
- Pop a city. If it was already visited, skip it.
- Otherwise, mark it as visited and push its unvisited neighbors.
- Repeat until the stack is empty.
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
public List<String> dfs(String start) {
  List<String> order = new ArrayList<>();
  Set<String> visited = new HashSet<>();
  Deque<String> stack = new ArrayDeque<>();
  stack.push(start);

  while (!stack.isEmpty()) {
    String city = stack.pop();
    if (!visited.add(city)) continue; // already visited
    order.add(city);

    List<String> neighbors = adjacency.get(city);
    // push in reverse, so the first neighbor is popped and explored first
    for (int i = neighbors.size() - 1; i >= 0; i--) {
      if (!visited.contains(neighbors.get(i))) {
        stack.push(neighbors.get(i));
      }
    }
  }
  return order;
}
Set.add returns false when the element is already in the set, so if (!visited.add(city)) checks and marks a city in one step. Use ArrayDeque as the stack. Java’s old Stack class is synchronized and slower, and its documentation recommends Deque instead.
Starting from Berlin, graph.dfs("Berlin") returns:
1
[Berlin, Magdeburg, Hannover, Bremen, Dortmund, Frankfurt, Stuttgart, München, Nürnberg, Leipzig, Dresden, Rostock]
This is the numbering in the diagram above. DFS goes from Berlin to its first neighbor, Magdeburg, then Hannover, then Bremen. Bremen is a dead end, so it backs up to Hannover and continues to Dortmund, Frankfurt, Stuttgart and München. From München it reaches Nürnberg, Leipzig and Dresden. Only at the very end does it come back to Berlin’s last neighbor, Rostock, which is right next to the start. That’s the depth-first idea: finish one branch completely before starting the next.
Because the visited cities are kept in a local Set and not inside the graph, you can call dfs again, or from another city, and get a correct result every time. From Hannover the order is [Hannover, Magdeburg, Berlin, Leipzig, Dresden, Nürnberg, München, Stuttgart, Frankfurt, Dortmund, Rostock, Bremen].
Recursive DFS
The call stack can replace the explicit stack. The recursive version is shorter and produces the same order:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
public List<String> dfsRecursive(String start) {
  List<String> order = new ArrayList<>();
  visit(start, new HashSet<>(), order);
  return order;
}

private void visit(String city, Set<String> visited, List<String> order) {
  visited.add(city);
  order.add(city);
  for (String neighbor : adjacency.get(city)) {
    if (!visited.contains(neighbor)) {
      visit(neighbor, visited, order);
    }
  }
}
The recursive version is easier to write in an interview. The iterative version is safer for very large graphs: a path of tens of thousands of vertices can throw a StackOverflowError in the recursive one.
Complexity of DFS
DFS visits every vertex once and looks at every edge twice, once from each end, so it takes O(V + E) time with an adjacency list. With an adjacency matrix, finding the neighbors of each vertex means scanning a whole row, so it takes O(V²). The visited set and the stack take O(V) extra space. For how to reason about these numbers, see Big O notation in Java.
DFS and BFS are the start of a whole family of graph algorithms: shortest paths with weights, minimum spanning trees, and directed graphs. Algorithms by Robert Sedgewick and Kevin Wayne has a full chapter on graphs, with clear Java implementations of DFS, BFS and these applications, and it’s the book I’d recommend for going further.
Finding a path with DFS
To find a route between two cities, DFS keeps the current path and removes a city when it backs up from a dead end:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
public List<String> findPath(String from, String to) {
  List<String> path = new ArrayList<>();
  return findPath(from, to, new HashSet<>(), path) ? path : List.of();
}

private boolean findPath(String city, String to, Set<String> visited, List<String> path) {
  visited.add(city);
  path.add(city);
  if (city.equals(to)) return true;
  for (String neighbor : adjacency.get(city)) {
    if (!visited.contains(neighbor) && findPath(neighbor, to, visited, path)) {
      return true;
    }
  }
  path.remove(path.size() - 1); // dead end: back up
  return false;
}
graph.findPath("Berlin", "München") returns:
1
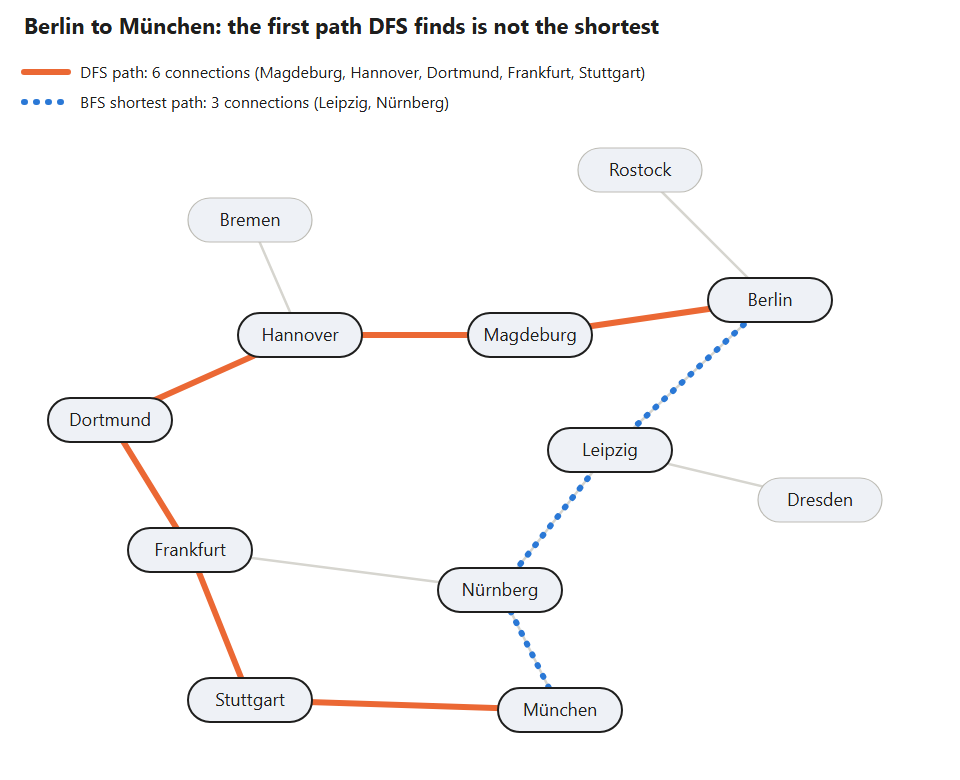
[Berlin, Magdeburg, Hannover, Dortmund, Frankfurt, Stuttgart, München]
That’s a valid route, but it takes 6 connections. Going through Leipzig and Nürnberg takes only 3. DFS returns the first path it finds, and which one that is depends on the order of the neighbors, not on the length of the path. DFS does not find the shortest path.
Breadth-first search: the shortest path
Breadth-first search (BFS) visits the graph in layers: first the start city, then all its neighbors, then all their neighbors, and so on. It uses a queue, a first-in, first-out structure, instead of a stack. Because it reaches every city at distance 1 before any city at distance 2, the first time it reaches a city is always along a path with the fewest connections.
To rebuild the path, BFS remembers from which city it reached each city:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
public List<String> shortestPath(String from, String to) {
  Map<String, String> previous = new HashMap<>();
  Set<String> visited = new HashSet<>(List.of(from));
  Deque<String> queue = new ArrayDeque<>(List.of(from));

  while (!queue.isEmpty()) {
    String city = queue.poll();
    if (city.equals(to)) {
      LinkedList<String> path = new LinkedList<>();
      for (String c = to; c != null; c = previous.get(c)) {
        path.addFirst(c);
      }
      return path;
    }
    for (String neighbor : adjacency.get(city)) {
      if (visited.add(neighbor)) {
        previous.put(neighbor, city);
        queue.offer(neighbor);
      }
    }
  }
  return List.of(); // not reachable
}
graph.shortestPath("Berlin", "München") returns [Berlin, Leipzig, Nürnberg, München], 3 connections:
The full BFS visiting order from Berlin shows the layers: [Berlin, Magdeburg, Leipzig, Rostock, Hannover, Dresden, Nürnberg, Bremen, Dortmund, München, Frankfurt, Stuttgart]. Berlin’s three neighbors come first, then the cities two connections away, and so on.
BFS finds the path with the fewest edges. If the edges have weights, such as kilometers or minutes, the shortest route is the one with the smallest total weight, and you need Dijkstra’s algorithm instead.
DFS vs BFS
| Depth-first search (DFS) | Breadth-first search (BFS) | |
|---|---|---|
| Data structure | Stack (or recursion) | Queue |
| Explores | One branch to the end, then backs up | Layer by layer, nearest vertices first |
| Shortest path in an unweighted graph | No | Yes |
| Time | O(V + E) | O(V + E) |
| Extra memory | O(depth of the search) for the recursion | O(width of the widest layer) for the queue |
| Typical uses | Cycle detection, topological sort, connected components, mazes, backtracking | Shortest path, nearest neighbors, levels in a tree or a social network |
What DFS is used for
Connected components. Run DFS from every city not yet visited, and count how many times you start. Our network has 1 component. Add an isolated city such as Sylt, an island with no Hyperloop connection, and the count becomes 2.
1
2
3
4
5
6
7
8
9
10
11
public int countComponents() {
  Set<String> visited = new HashSet<>();
  int components = 0;
  for (String city : adjacency.keySet()) {
    if (!visited.contains(city)) {
      components++;
      visit(city, visited, new ArrayList<>());
    }
  }
  return components;
}
Cycle detection. In an undirected graph, DFS finds a cycle when it reaches a visited city that isn’t the one it just came from. On our network it returns true, because of the Frankfurt–Nürnberg–München–Stuttgart loop. On the 11 connections without Frankfurt–Nürnberg and Stuttgart–München, which form a tree, it returns false.
1
2
3
4
5
6
7
8
9
10
11
private boolean hasCycle(String city, String parent, Set<String> visited) {
  visited.add(city);
  for (String neighbor : adjacency.get(city)) {
    if (!visited.contains(neighbor)) {
      if (hasCycle(neighbor, city, visited)) return true;
    } else if (!neighbor.equals(parent)) {
      return true; // a visited neighbor that isn't where we came from
    }
  }
  return false;
}
Ordering tasks (topological sort). In a directed graph of tasks, where an edge means “must be done before”, DFS can put the tasks in a valid order. Add each task to the front of the result after all the tasks that depend on it are finished:
1
2
3
4
5
6
7
static void sortVisit(String task, Map<String, List<String>> tasks, Set<String> visited, Deque<String> order) {
  visited.add(task);
  for (String next : tasks.getOrDefault(task, List.of())) {
    if (!visited.contains(next)) sortVisit(next, tasks, visited, order);
  }
  order.push(task); // all tasks that depend on this one are already in the result
}
For a small project where Design API comes before Write code and Write docs, Write code before Run tests, and both Run tests and Write docs before Deploy, it returns [Design API, Write docs, Write code, Run tests, Deploy]. Build tools such as Maven and Gradle solve the same problem when they decide in which order to build modules that depend on each other.
FAQ
Does DFS find the shortest path?
No. DFS finds a path, and which one depends on the order of the neighbors. In our network, DFS goes from Berlin to München in 6 connections, while the shortest route takes 3. Use BFS for the shortest path in an unweighted graph, and Dijkstra’s algorithm when edges have weights.
What is the time complexity of DFS?
O(V + E) with an adjacency list, where V is the number of vertices and E the number of edges, because every vertex and every edge is processed a constant number of times. With an adjacency matrix it’s O(V²).
Should I use recursion or a stack for DFS?
In an interview, recursion is shorter and clearer. In production code that can see very deep graphs, use an explicit ArrayDeque as a stack to avoid a StackOverflowError.
Why do I need a visited set?
Graphs can have cycles. Without remembering the visited vertices, DFS would go round a cycle forever. Keep the set outside the vertex objects, as a local variable, so the graph can be searched many times and by several threads.
Is DFS the same as preorder traversal of a tree?
Preorder traversal is DFS on a tree: visit the node, then its children, one subtree at a time. A tree has no cycles, so it doesn’t need a visited set.
Graph questions are interview favorites because they test data structures and algorithms together. My book THE CODE INTERVIEW: Real Java Coding Interview Questions, Solved Step by Step includes breadth-first search with an adjacency list built on a LinkedList, solved step by step in Java.
“If this article helped you, help me create the next one.”
☕ Buy me a coffee